Margin of Error Does Not Include Every Kind of Survey Error
TLDR
The central margin of error survey limitations are straightforward: a conventional margin of error estimates uncertainty caused by observing a probability sample instead of the entire target population. It does not fully account for people missing from the sampling frame, differences between respondents and nonrespondents, confusing questions, collection-mode effects, data-processing mistakes, or bias that weighting fails to correct. Treat the ± figure as a measure of sampling precision, not a complete grade for survey accuracy.
A result of 52% with a reported margin of error of ±3 percentage points may look precise. But that figure answers only a limited question: how much might the estimate vary because researchers surveyed a sample rather than every member of the target population, under the survey’s stated assumptions? A small margin of error can coexist with a systematically unrepresentative sample or a poorly measured outcome.
What a margin of error actually measures
Sampling error arises because different samples drawn from the same population will contain different people and produce different estimates. A conventional margin of error translates the estimated standard error into a range at a stated confidence level. It is most directly applicable to probability samples, in which population members have known selection probabilities under the sampling design.
Several related terms need to remain distinct:
- Estimate: The value calculated from the responding sample, such as 52% supporting a policy.
- Standard error: An estimate of how much the survey estimate would vary across repeated samples under the design and assumptions.
- Confidence level: The long-run coverage level attached to the interval procedure, such as 90% or 95%.
- Margin of error: The distance added to and subtracted from the estimate to form a confidence interval under specified conditions.
- Confidence interval: The estimate plus or minus its margin of error.
The confidence level cannot be inferred safely from the ± number alone. Although 95% intervals are common in public reporting, they are not universal. American Community Survey materials, for example, use a 90% confidence convention and calculate the margin of error as 1.645 times the standard error in that context. Readers should therefore look for both the margin and its confidence level.
The calculation must also reflect the actual sample design. Stratification, clustering and unequal weights can change variance relative to a simple random sample. A margin calculated as though the survey used a simple random sample may overstate its precision when those design features increase variance. The American Association for Public Opinion Research’s guide to understanding polls and surveys recommends checking whether reported sampling-error estimates account for design effects.
The key margin of error survey limitations
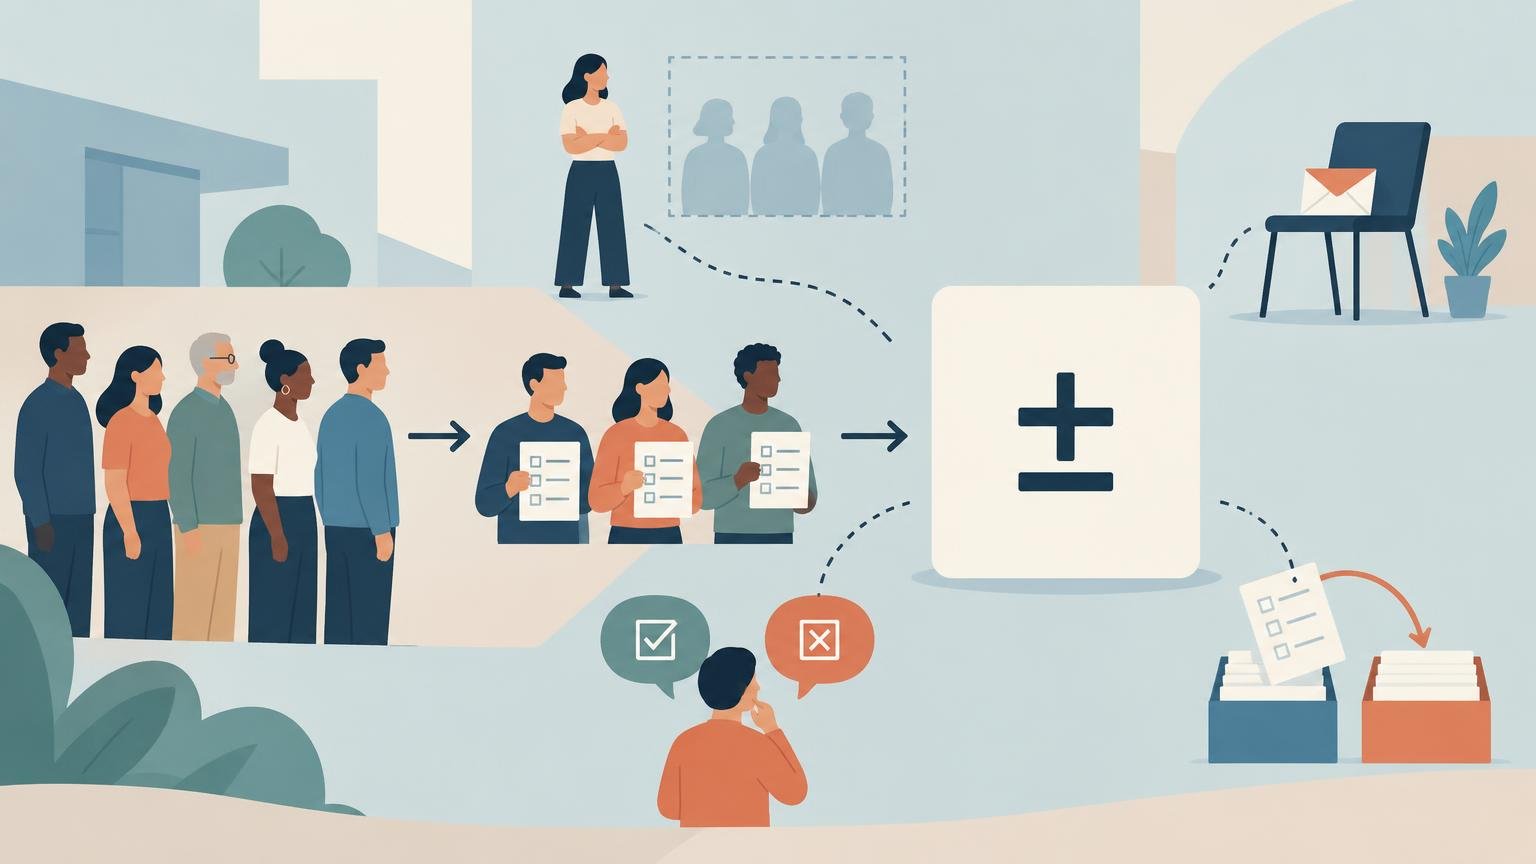
The easiest way to interpret a margin of error is to separate precision from total accuracy. Sampling uncertainty is one component of survey error. Coverage, nonresponse, measurement and processing can also move an estimate away from the value researchers intended to measure, but they are not rolled into a conventional margin of error as a complete total-error statistic.
| Error source | What can go wrong | Included in conventional MOE? |
|---|---|---|
| Sampling error | The selected sample differs by chance from the target population | Yes, under the stated design and assumptions |
| Coverage error | The sampling frame omits, duplicates or wrongly includes population members | No |
| Nonresponse error | Respondents and nonrespondents differ in ways related to the estimate | No |
| Measurement error | Answers are affected by wording, recall, question order or collection mode | No |
| Processing error | Coding, editing, imputation or other handling changes the result incorrectly | No |
| Residual weighting problems | Adjustments do not fully remove representation differences | No, although weights should affect variance estimation |
Coverage error: who had a chance to be selected?
A survey first needs a usable connection between its target population and its sampling frame. Coverage error occurs when that frame excludes eligible people, contains ineligible people or duplicates units. For example, a survey intended to represent all residents cannot accomplish that goal merely by drawing a large sample from a list that systematically misses some residents.
Coverage is about reach, not just sample count. Increasing the number of observations from the same incomplete frame can narrow sampling uncertainty while leaving the underlying coverage problem in place. The resulting estimate may be more numerically precise without becoming more representative.
Nonresponse error: who did not participate?
Nonresponse becomes consequential when the people who respond differ from the people who do not respond in ways related to the measured outcome. A low response rate can be a warning sign, but the rate by itself does not reveal the size or direction of nonresponse bias. Conversely, a higher response rate is not proof that the respondents and nonrespondents are equivalent.
The practical question is not simply “How many people answered?” It is “Could participation be related to the result?” A customer survey completed mainly by people with unusually strong opinions may produce a distorted satisfaction estimate even when its respondent count generates a narrow nominal margin of error. This same distinction matters when interpreting compressed survey measures such as Net Promoter Score and its limitations.
Measurement error: what did the answers mean?
A representative sample cannot rescue a question that measures the wrong thing. Respondents may interpret wording differently, forget relevant details, answer in socially acceptable ways or react to the order in which questions are presented. Telephone, web, mail and in-person collection can also produce different response patterns. Census methodology treats question wording, recall, collection procedures and mode effects as measurement-error considerations.
Suppose two surveys ask about household finances. One asks whether respondents are “financially secure,” while another asks whether they could cover a specific emergency expense. Both may be conducted well, but they are measuring different concepts. Comparing their percentages as though the wording were interchangeable creates a problem no sampling margin can quantify.
Processing error: what happened after collection?
Survey data rarely move directly from raw answers to a published percentage. Responses may be coded, edited, checked, imputed when values are missing, weighted and tabulated. Errors introduced during these stages are processing errors.
Processing is not inherently a flaw; these steps are often necessary to produce usable data. The issue is whether the procedures were appropriate, documented and implemented correctly. A polished final table and a small margin of error do not independently verify the coding rules or treatment of missing answers.
Weighting can help, but it is not a guarantee
Survey weights can account for unequal selection probabilities and adjust the responding sample toward population benchmarks. For example, a respondent selected with a lower probability may receive more weight, while calibration can align selected characteristics of the weighted sample with known population totals.
Weighting is an adjustment, not evidence that every source of bias has disappeared. It works best when the variables used for adjustment are meaningfully related to participation and the outcome being estimated. Differences that were not measured, were measured poorly or were not included in the adjustment can remain.
Weights also affect precision. When some observations receive much more weight than others, the effective information in the sample can be lower than the raw respondent count suggests. Variance estimation should account for weighting and other design features rather than treating all completed interviews as independent, equally weighted observations.
Why a bigger sample does not fix every problem
Larger probability samples generally reduce sampling uncertainty when the design and measured population remain comparable. That is why sample size has a visible relationship with the margin of error. But the relationship applies to sampling variance, not automatically to total survey accuracy.
Imagine that an online survey draws 1,000 respondents from a frame that undercovers a consequential group. Expanding it to 10,000 respondents from the same frame can produce a much tighter sampling interval. It does not, by itself, add the people who had no chance to be selected. The survey has become more precise about the population represented by its frame, but not necessarily more accurate for its intended target population.
The same logic applies to measurement. Repeating an ambiguous question with more respondents reduces random sampling variation around the answers to that question. It does not make the question less ambiguous. Sample size should therefore be assessed alongside frame quality, response patterns, questionnaire design and processing methods.
Probability samples and nonprobability samples require different language
Conventional margins of sampling error rest on probability-sampling concepts. Some opt-in panels and other nonprobability samples instead publish a “credibility interval” or another modeled uncertainty measure. AAPOR distinguishes these model-dependent intervals from conventional probability-sample margins of sampling error.
That distinction does not automatically make every nonprobability survey unusable. It means the uncertainty number depends on modeling assumptions rather than known selection probabilities alone. Readers should check how participants were recruited, which model generated the interval, what population benchmarks were used and whether the publisher clearly labels the measure. Calling every ± figure a margin of error hides those differences.
Do not compare two estimates by looking only at their MOEs
A common shortcut is to declare two estimates different when their confidence intervals do not overlap, or equivalent when they do. Neither rule is universal. The uncertainty of a difference depends on the variances of both estimates and, in some comparisons, their covariance. Complex survey design can further affect that calculation.
For comparisons across groups, years or questions, look for a directly reported difference, standard error or significance test that uses the survey’s design-aware variance method. Also verify that the populations, questions, field periods and collection modes are comparable. A statistically distinguishable difference can still be too small to matter in practice, while an important-looking difference may be too uncertain to support a firm conclusion.
A practical checklist for reading any survey
A trustworthy survey report should provide enough methodology for readers to understand what the estimate represents. AAPOR’s transparency guidance emphasizes disclosure of sample recruitment, question wording, weighting and the treatment of design effects, among other methodological details. Before relying on a headline percentage, ask:
- Target population: Who was the survey intended to represent?
- Sampling frame: What list, panel, address system or recruitment method gave people a chance to participate?
- Sample type: Was it a probability sample or a nonprobability sample?
- Sample base: How many eligible respondents answered the specific question, including for any subgroup being discussed?
- Confidence convention: What confidence level accompanies the margin of error?
- Survey design: Does the uncertainty estimate reflect clustering, stratification and unequal weighting?
- Coverage: Which groups might have been omitted, duplicated or difficult to reach?
- Participation: How were response or completion metrics defined, and could response propensity relate to the outcome?
- Questionnaire: What were the exact wording, response options and question order?
- Timing and mode: When was the survey fielded, what reference period did it use, and was collection conducted online, by telephone, by mail or in person?
- Weighting: Which benchmarks and adjustment variables were used?
- Processing: How were missing answers, coding, editing, imputation and tabulation handled?
- Comparison method: For differences between estimates, did the publisher provide a direct, design-aware test or variance estimate?
Not every report will answer every question in its headline or summary. The important point is whether the underlying methodology is available and whether the missing details could change the interpretation. An unexplained ± figure should prompt more questions, not end the analysis.
The useful takeaway
Margin of error is valuable because it prevents a sample estimate from being presented as perfectly exact. But its scope is narrower than the phrase “error” may suggest. It usually communicates sampling precision under a particular design, variance method and confidence level—not the combined effect of everything that could make a survey wrong.
Read the margin of error, then examine the target population, frame, recruitment, response patterns, exact questions, collection mode, weighting and processing. If those elements are sound and transparent, the ± figure becomes informative. If they are weak or undisclosed, a small margin of error can offer false reassurance. The best next step is to open the methodology report before repeating the headline number.
References
- Calculation : U.S. Bureau of Labor Statistics
- A Journalist’s Guide to Understanding Polls & Surveys – AAPOR
- Statistical Testing Tool
- American Community Survey Design and Methodology
- Statistical Quality Standard D3: Producing Measures and Indicators of Nonsampling Error
- Chapter 15: Improving Data Quality by Reducing Nonsampling Error
- CPS Response Rates : U.S. Bureau of Labor Statistics
- Weighting
- Understanding a “credibility interval” and how it differs from the “margin of sampling error” in a public opinion poll – AAPOR
- American Community Survey Variance Replicate Estimate Tables
- Transparency Initiative – AAPOR