Confidence Interval vs Prediction Interval: Estimating a Mean Is Not Predicting the Next Observation
TLDR
Use a confidence interval when the question concerns an unknown mean, expected response, or model parameter. Use a prediction interval when the question concerns one new or future observation. In ordinary linear regression, the prediction interval is wider because it must account for both uncertainty in the estimated mean and the natural case-to-case variation around that mean. A narrow confidence band around a fitted line is therefore not a plausible range for individual outcomes.
The most useful rule in the confidence interval vs prediction interval decision is simple: match the interval to the noun in the question. “What is the average?” calls for a confidence interval. “What might happen to the next case?” calls for a prediction interval. Confusing those questions can turn a statistically correct chart into a materially misleading forecast.
The difference in one example
Suppose a delivery company models delivery time from distance. At a distance of five miles, its fitted regression model estimates an average delivery time of 31 minutes. With enough comparable orders, the company might estimate that mean quite precisely. A confidence interval for the mean response could consequently form a narrow band around the fitted line.
That does not mean the next five-mile delivery will finish close to 31 minutes. One order may be ready when the courier arrives; another may still be in preparation. Traffic, weather, building access, courier availability, and other order-level factors can add substantial variation. A prediction interval for one new delivery must include that variability as well as uncertainty about the mean.
The distinction is between two separate quantities:
- Mean-response uncertainty: How precisely has the average delivery time for five-mile orders been estimated?
- Individual-outcome variability: How far might one new five-mile order fall above or below that average?
A large dataset can reduce the first quantity without eliminating the second. That is why a narrow confidence interval can coexist with highly variable individual outcomes.
What a confidence interval estimates
A confidence interval quantifies uncertainty about an unknown parameter or expected response. Depending on the analysis, the target could be a population mean, a regression coefficient, or the mean response at a specified predictor value. In regression, a confidence band around the fitted line commonly represents uncertainty about the regression function rather than the spread of future data points.
Return to the delivery example. If managers want to know the average delivery time for all comparable five-mile orders, a confidence interval for the mean response fits the question. It helps assess the location of the expected outcome, not the likely range of every delivery.
The same distinction appears in survey reporting. A margin of error may quantify sampling uncertainty around an estimated population value, but it does not describe every source of survey error or the range of individual responses. Our guide to what a survey margin of error leaves out explains that broader measurement issue.
What a prediction interval predicts
A prediction interval gives a range for a new observation under the fitted model. The new outcome is itself random, so the interval needs to reflect the unexplained variation among individual cases in addition to uncertainty in the fitted mean.
For the delivery model, the relevant question becomes: “Given a new five-mile order with the specified predictor values, what range should we expect its delivery time to fall within?” That is an individual-outcome question. A confidence interval for average delivery time cannot answer it.
Prediction intervals can also be constructed for more than one future observation or for a future average, but the target must be stated. Predicting the average of 100 future deliveries is not the same task as predicting one delivery. Averaging many future outcomes reduces some of the case-level variation in the average; predicting one case does not receive that benefit.
Why the prediction interval is wider
In ordinary simple linear regression, the confidence interval for the mean response and the prediction interval for a new individual response are centered on the same fitted value. The difference lies in their standard errors.
At a predictor value x₀, the standard-error terms can be summarized as follows:
- Mean response: s × √[1/n + (x₀ − x̄)²/Sxx]
- New observation: s × √[1 + 1/n + (x₀ − x̄)²/Sxx]
Here, s represents the estimated residual standard deviation, n is the sample size, x̄ is the sample mean of the predictor, and Sxx summarizes the observed spread of predictor values around that mean. The exact interval also applies an appropriate critical value.
The important difference is the extra 1 inside the prediction expression. It represents residual variation for a new observation. Collecting more data can shrink the terms associated with estimating the regression mean, but it does not automatically make individual outcomes stop varying around that mean. At the same predictor value and nominal coverage level, the resulting prediction interval is therefore wider than the corresponding confidence interval for the mean response.
How to read confidence and prediction bands on a chart
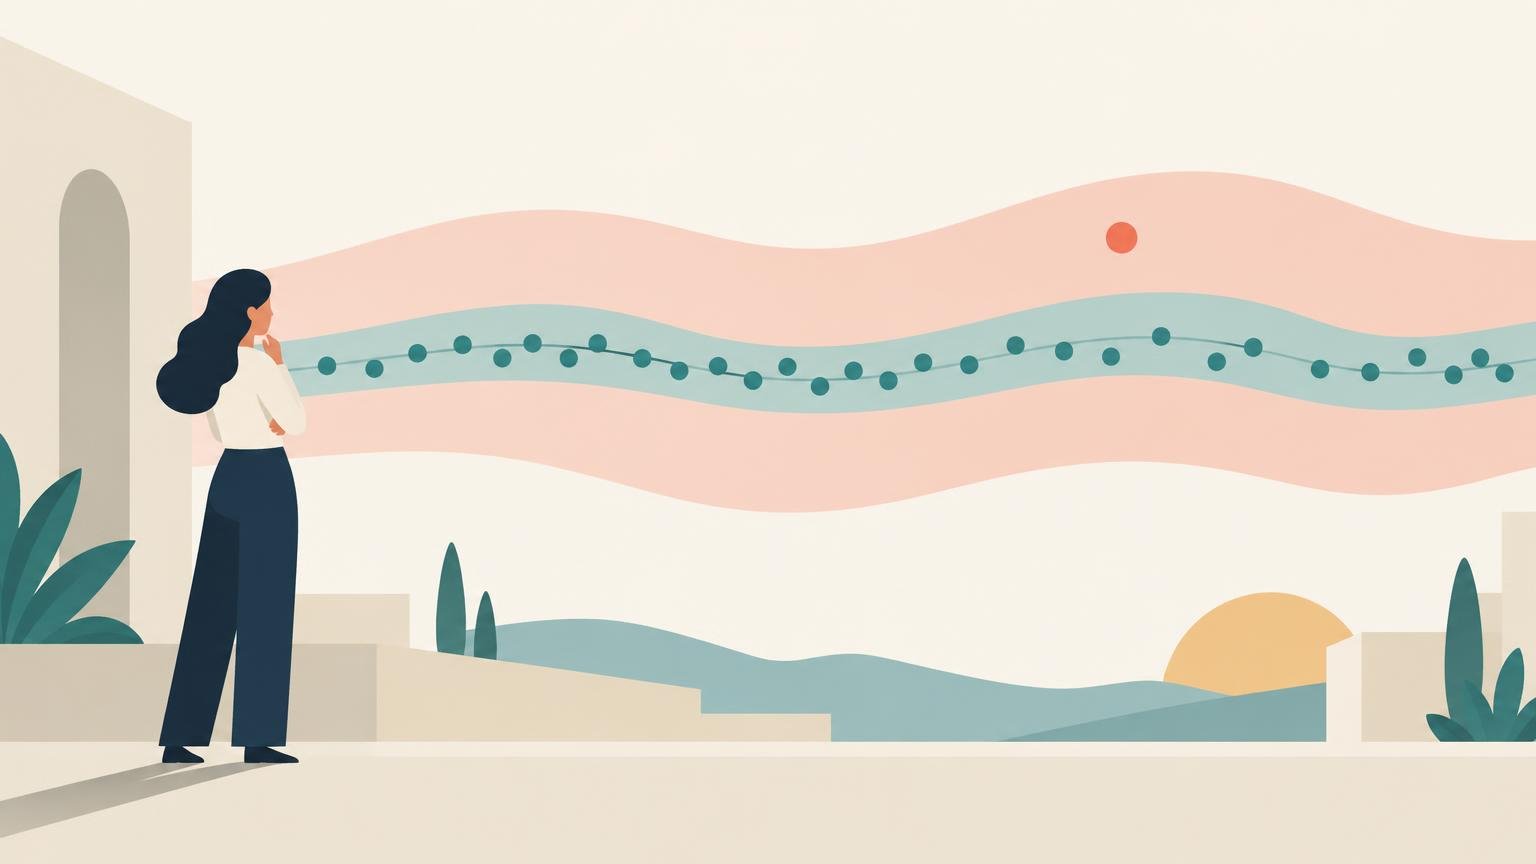
A regression chart may contain four distinct elements: observed points, a fitted line, a confidence band, and a prediction band. Read each one separately.
- Observed points show the outcomes actually recorded in the sample.
- The fitted line shows the model’s estimated mean response at each predictor value.
- The confidence band shows uncertainty about that fitted mean response.
- The prediction band shows the expected uncertainty around a new individual observation under the model.
The observed points will usually be much more dispersed than the confidence band around the line. That is not a contradiction. The band and the points represent different quantities. If a dashboard displays only the narrow confidence band, its label should make clear that the band concerns the estimated average. It should not be described as where individual results are expected to fall.
Both confidence and prediction intervals tend to widen as the predictor moves away from the mean of the observed predictor values. The model has the most information near the center of the data and less leverage for estimating the relationship near the edges. A band that flares outward is therefore often communicating increasing estimation uncertainty, not merely a design choice.
What “95%” means
For a conventional frequentist 95% confidence interval, the percentage describes the long-run performance of the interval-producing procedure. If the same sampling and interval-construction process were repeated many times under the model assumptions, about 95% of the resulting intervals would contain the fixed target parameter. Strictly speaking, after one interval has been calculated, frequentist theory does not assign a 95% probability to that fixed parameter being inside that particular interval. The parameter is treated as fixed; the interval procedure is what varies across samples. NIST’s explanation of confidence limits
A 95% prediction interval has a related coverage interpretation for new observations under the fitted model and its assumptions. It does not guarantee that every future case will be captured. Across repeated applications in comparable conditions, the procedure is intended to attain its stated coverage.
Coverage also needs a defined scope. A pointwise 95% band targets coverage separately at a specified predictor value. A simultaneous band is designed to cover an entire regression function over a stated range. Showing many pointwise intervals across a chart does not automatically turn them into a simultaneous 95% band.
Choose the interval by the decision
| Question | Appropriate output | What it describes |
|---|---|---|
| What is the average outcome at this predictor value? | Confidence interval for the mean response | Uncertainty about the expected or average outcome |
| What might happen to the next individual case? | Prediction interval | Uncertainty around one new observation |
| What range contains a stated proportion of the population? | Tolerance interval | Population coverage with a stated confidence level |
| What values might occur later in a time series? | Forecast interval | Future time-indexed values under a forecasting model |
| What values are plausible for a parameter in a Bayesian model? | Credible interval | Posterior probability under the model and prior |
These labels are not interchangeable. In particular, a tolerance interval concerns a specified proportion of a population at a stated confidence level, whereas a prediction interval concerns new measurement or measurements. A time-series forecast interval must account for the structure and horizon of a forecasting problem. A Bayesian credible interval has a different probability interpretation from a frequentist confidence interval.
When a dashboard should show one band or both
Show a confidence band when readers need to compare estimated averages or inspect uncertainty in a trend. For example, analysts might use it to communicate the expected mean delivery time by distance or the estimated average relationship between price and demand.
Show a prediction band when readers are making case-level plans. A customer asking when one order might arrive, an operator planning capacity for the next job, or a risk manager evaluating the possible result of one future case needs individual-outcome uncertainty.
Show both when the difference is itself decision-relevant. The narrow inner band can represent uncertainty in the estimated mean, while the wider outer band represents uncertainty for a new observation. Use direct labels such as “95% confidence interval for mean delivery time” and “95% prediction interval for one delivery.” Labels such as “uncertainty range” are too vague when two materially different ranges are possible.
Model problems can make either interval misleading
The usual regression formulas do not create valid coverage by themselves. Their interpretation depends on the model and residual assumptions being adequate for the task. Nonlinearity, nonconstant residual variance, dependence, influential observations, omitted structure, and other regression problems can produce intervals with misleading coverage, including bands that are too narrow in parts of the predictor range.
Before presenting an interval, check the following:
- Target: Is the output about a parameter, a mean response, one new case, or a population proportion?
- Coverage: Is the stated level 90%, 95%, 99%, or something else?
- Scope: Is the interval pointwise or simultaneous?
- Residual behavior: Does the unexplained spread change across fitted values or predictor levels?
- Dependence: Are observations independent, or does clustering or time order require a different model?
- Range: Is the requested prediction within the observed predictor range?
- Conditions: Will the new case arise under conditions comparable to those used to fit the model?
Software output should also be read carefully. For example, statsmodels distinguishes standard errors for a predicted mean from standard errors for observations and provides separate confidence and prediction interval functionality. The statsmodels prediction-results documentation Selecting the wrong output column can recreate the conceptual mistake even when the model itself is correctly fitted.
Why extrapolation needs extra caution
Regression intervals are usually most defensible within the predictor range represented by the data. Extending the fitted relationship beyond that range assumes the same functional pattern continues where it has not been observed. That assumption may fail even if the line fits the sampled data well.
The interval may widen outside the data range, but a wider formula-based band does not protect against an incorrect model form. If delivery distances in the dataset run from one to ten miles, predicting a 50-mile delivery is not merely a less precise version of predicting a five-mile delivery. The operating process may change entirely.
The practical takeaway
When reviewing a chart or statistical report, first identify the quantity inside the interval. If it is an unknown mean, expected response, or parameter, the confidence interval may be appropriate. If it is one new outcome, use a prediction interval. If it concerns a stated share of a population, investigate a tolerance interval instead.
Do not turn a narrow confidence band into an individual-level forecast, delivery promise, performance range, or risk limit. The average can be estimated precisely while the next observation remains highly uncertain. The right next step is to rewrite the reporting question in plain language—“average outcome” or “next individual outcome”—and then verify that the displayed interval answers that exact question.
References
- 4.1.3.2. Prediction
- 3 SLR Estimation & Prediction – STAT 501 | Regression Methods
- 1.3.5.2. Confidence Limits for the Mean
- 12 Multicollinearity & Other Regression Pitfalls – STAT 501 | Regression Methods
- statsmodels.regression.linear_model.PredictionResults — statsmodels 0.15.0
- 9 Linear Regression Foundations – STAT 500 | Applied Statistics